

NVIDIA has published new AI infrastructure efficiency results showing its DSX MaxLPS power-management technology increased cluster-wide token throughput by 24% in its first validation on Blackwell servers. Announced at the AI Infra Summit on September 15, the results also showed a 23% improvement in performance per watt, while NVIDIA detailed further efficiency gains expected from its next-generation Vera Rubin platform. The company is positioning tokens generated per megawatt, rather than raw peak compute, as an increasingly important measure for large-scale AI infrastructure.
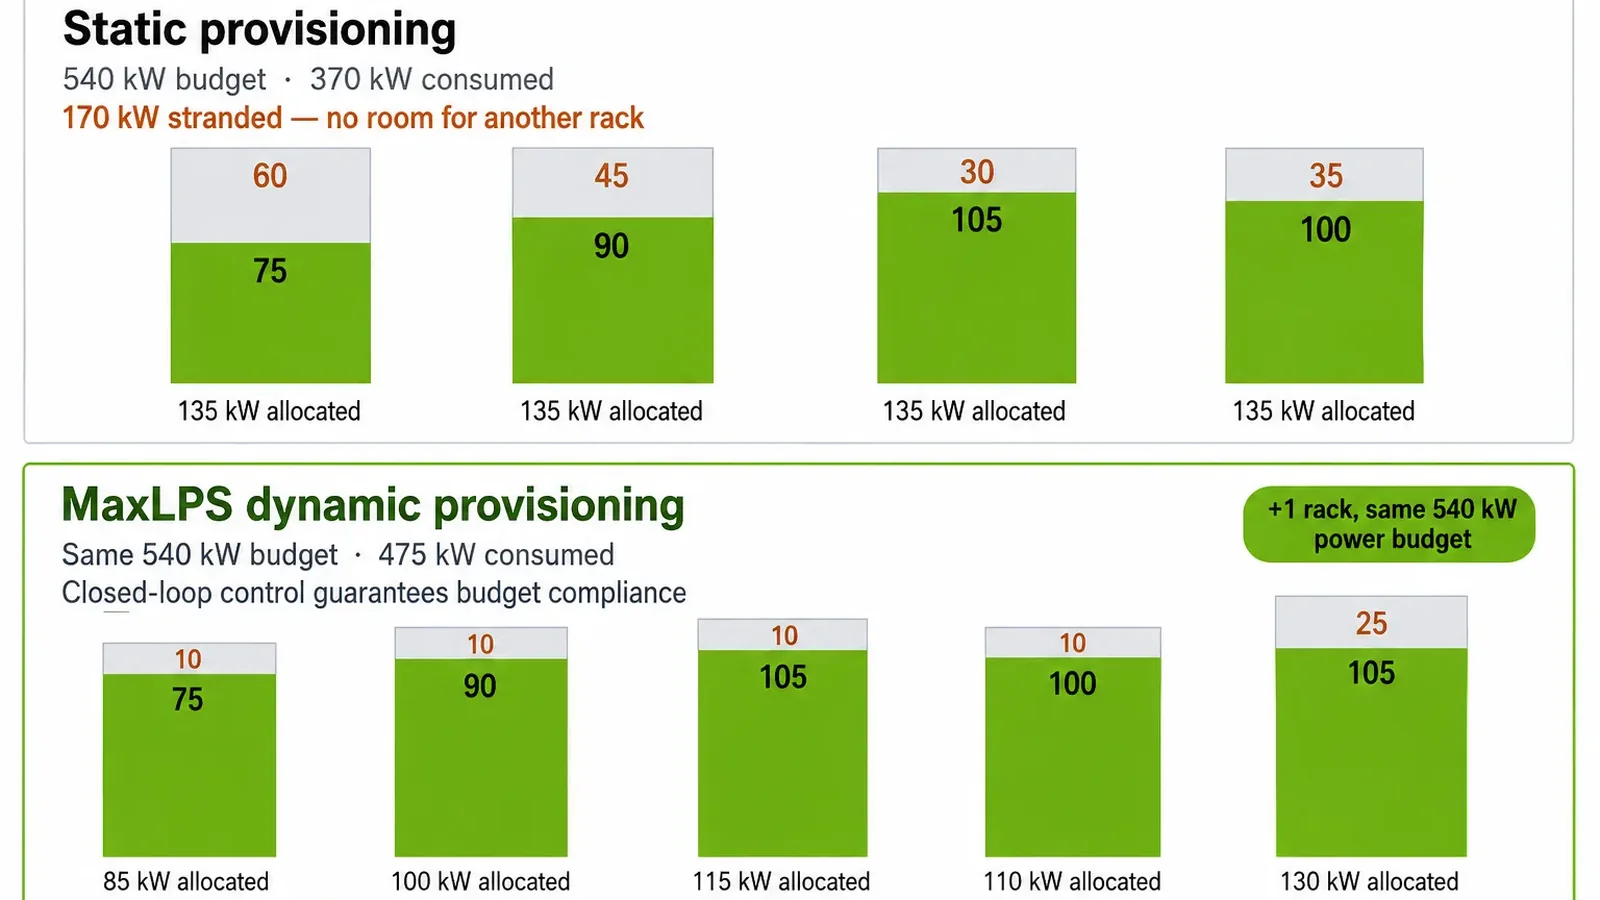
AI cloud provider Lambda carried out the first validation of DSX MaxLPS on NVIDIA Blackwell servers. Using the same power budget normally allocated to 16 full-power nodes, Lambda operated 19 nodes and increased aggregate throughput from roughly 4 million to 5 million tokens per second. DSX MaxLPS does this by continuously monitoring power use across GPUs and racks, moving available power toward workloads that need it while reclaiming capacity that would otherwise remain unused under static provisioning.
NVIDIA says the approach becomes even more important as AI data centers run mixtures of training and inference workloads with different power characteristics. Rather than reserving enough power for every system to operate at its theoretical peak simultaneously, MaxLPS dynamically redistributes capacity across the facility. In suitable Vera Rubin NVL72 deployments, NVIDIA says the technology can support up to 40% more GPU capacity within the same megawatt power budget and raise token throughput by as much as 35%.
The broader Vera Rubin results presented at the summit put those power-management gains alongside substantial improvements at the silicon and rack level. On SemiAnalysis’ AgentX benchmark, NVIDIA says Vera Rubin NVL72 delivered up to 30 times higher throughput per megawatt than GB300 NVL72 while running DeepSeek V4 Pro. AgentX uses recorded agentic coding sessions with growing context, tool calls and sub-agent activity rather than conventional single-request inference tests, making it more representative of the heavier workloads generated by autonomous AI systems.
NVIDIA says those AgentX results also translate to as much as 45 times lower cost per million tokens. The company attributes the improvement to full-stack changes including the 72-GPU NVL72 scale-up domain, sixth-generation NVLink, NVFP4 precision on fifth-generation Tensor Cores and software such as TensorRT LLM and NVIDIA Dynamo. The results build on NVIDIA’s wider push to improve the economics of AI inference, alongside its recent expansion of local AI hardware and inference software for smaller-scale deployments.
NVIDIA also highlighted Groq 3 LPX as part of its Vera Rubin inference platform. On a 100,000-context Qwen 3.8 27B workload, the company says the system reached 2,529 output tokens per second per user. Combining Vera Rubin, Groq 3 LPX and DSX power management is intended to address both throughput and latency as AI agents perform longer chains of reasoning and repeatedly invoke tools.
CPU results were another part of the announcement. Perplexity measured 1.9 times faster sandbox startup performance on NVIDIA Vera CPUs for its SPACE agent environment, while DeepInfra reported 2.2 times faster orchestration-step latency. Redpanda reported 5.5 times lower latency and 73% higher throughput in its testing, while Starburst measured three times faster query throughput; NVIDIA also cited performance results from ClickHouse, Prime Intellect and Kinetica.
Beyond compute efficiency, NVIDIA demonstrated how AI facilities can respond dynamically to electricity-grid conditions. Emerald AI and NVIDIA worked with Silicon Valley Power on a flexible-load program capable of responding to hundreds of grid demand signals while preserving priority AI workloads. NVIDIA’s DSX Flex software can reduce power consumption for lower-priority jobs during grid events and restore them afterward, turning large AI data centers into more controllable electricity loads rather than fixed consumers.
The announcements reflect NVIDIA’s increasingly broad definition of AI infrastructure, spanning processors, networking, power management, cooling and data-center operations. Its DSX platform is designed to optimize entire AI factories rather than individual servers, while Vera Rubin is now in production and beginning to generate third-party performance measurements. With power availability becoming a major constraint on new AI capacity, NVIDIA is arguing that how many useful tokens a facility can generate from each megawatt will matter as much as how many GPUs it contains.
